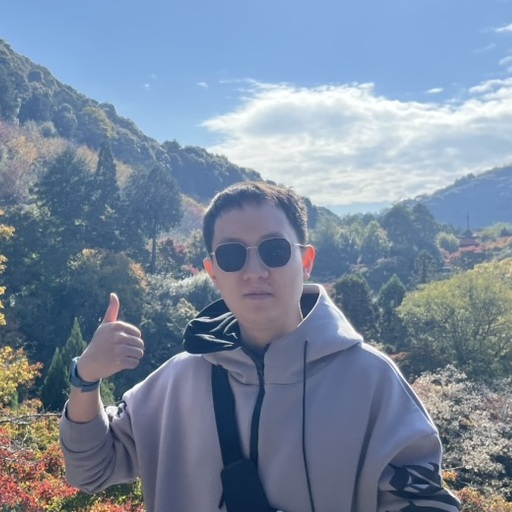
I have come to feel that the evaluation system built around papers can no longer capture a person. What someone has built, the questions they have chased, and the interests they have kept for years probably say more about them. I will keep adding more of my projects and interests to this homepage.
📖 Educations
Huazhong University of Science and Technology — Wuhan, China
Sep. 2019 - Jun. 2026, Ph.D. in Control Science and Engineering, School of Artificial Intelligence and Automation, advised by Prof. Yunfeng Luo.
Research areas: Large Language Model, Reinforcement Learning, Game Theory.
🧑💼 Work Experiences
ByteDance Seed — Doubao Post-Training (Jul. 2026 ~ Now)
Working on the post-training of Doubao large language models at ByteDance Seed. Focused on alignment and capability enhancement through supervised fine-tuning, RLHF / RLAIF, and reasoning-oriented reward modeling, with the goal of pushing Doubao's instruction following, reasoning and tool-use abilities further.
📝 Publications
- Preference-CFR Beyond Nash Equilibrium for Better Game Strategies. (ICML 2025) Proposes the Preference Counterfactual Regret Minimization (Pref-CFR) algorithm to achieve diverse Nash equilibria, enabling customizable strategies by incorporating preference and vulnerability parameters. Demonstrates distinct play styles in Texas Hold’em without sacrificing strategic strength.
- Accelerating Nash Equilibrium Convergence in Monte Carlo Settings Through Counterfactual Value Based Fictitious Play (NeurIPS 2024). Introduces the Monte Carlo Counterfactual Value-Based Fictitious Play (MCCFVFP) algorithm for large-scale games, achieving 20–50\% faster convergence than standard MCCFR in complex settings like Texas Hold’em.
- Real-Time Weighted Fictitious Play: Converging to Equilibrium at the Speed of $O(T^{-1})$ in Games. Presents the Real-Time Weighted Fictitious Play (RTWFP) algorithm with $O(T^{-1})$ convergence in two-player zero-sum games, extending to correlated equilibrium and continuous-time FP. Outperforms existing algorithms in scalability and speed.
- ELO-Rated Sequence Rewards: Advancing Reinforcement Learning Models. Proposes ELO-Rated Sequence Rewards (ERRL), which uses ordinal preferences and ELO ratings to replace numerical rewards, achieving superior performance in long-term RL tasks like Atari benchmarks.
💻 Internship Experiences
ByteDance Seed — LLM Post-training Based on Games (Jun. 2025 ~ Oct. 2025)
- Project Goal: integrate game-theoretic problems into LLM post-training to enhance LLM capabilities.
- Project Results: delivered game-oriented LLM evaluation & training frameworks; trained an LLM Texas Hold'em AI that outperformed GPT-o3, Grok-4, etc., with improved instruction following.
- Personal Work: proposed a novel algorithm with an "LLM Reflection" mechanism that outperforms traditional RL methods in game scenarios; built the game-oriented LLM evaluation framework (integrated into the team's system) and a training framework based on Verl.
vivo — SD Model Fine-Tuning via Reinforcement Learning (Feb. 2025 ~ Apr. 2025)
- Project Goal: fine-tune Stable Diffusion with reinforcement learning to improve generation quality and prompt alignment.
- Project Results: early results show clear improvements in image quality, textual relevance and human preference alignment; ongoing work on reward design and distributed training scale-up.
- Personal Work: designed a composite reward model combining aesthetics, textual relevance, diversity and human feedback; tuned the RL training pipeline for SD.
Fen AI — Texas Hold’em AI (Sep. 2023 ~ Jan. 2024)
- Project Goal: create an AI that matches the performance of Pluribus, a renowned Texas Hold’em AI.
- Project Results: the final AI reached the level of professional players in two-player Texas Hold’em; the multi-player version is still under development.
- Personal Work: contributed to key algorithms (MCCFR, MCCFR pruning), built foundational components such as strategy storage and result visualization, and handled algorithm parameter tuning and testing.
ByteDance Nuverse — Reinforcement Learning Internship (Jul. 2021 ~ Mar. 2022)
- Project Goal: design multi-style AI companion NPCs for the game One Piece: Burning Will.
- Project Results: added a style evolution module on top of the previous AI training framework, leading to an 80–120% improvement in key indicators and clear style differentiation in play; several AIs reached deployable quality.
- Personal Work: served as the main executor of the project. Under my advisor's guidance, I implemented the multi-style AI algorithm and explored the integration of human preferences into reinforcement learning, which culminated in a research paper summarizing the findings and potential applications.
China Resources Group — Land Auction (Feb. 2021 ~ Jun. 2021)
- Project Goal: design a bidding strategy for China Resources Group in the “first/last” land auction.
- Project Results: the strategy was approved by China Resources Land Group and deployed in dozens of land auctions (each over $100M). The algorithm outperformed the group’s expert approach, boosting bid accuracy 3–4× and winning probability by ~5%, and was adopted as their standard land auction strategy.
- Personal Work: built a simulator of the “first/last” land auction from historical data and applied the Fictitious Play algorithm to develop strategies. Participated in three real auctions involving a total bidding scale of $1B, and refined the model based on real-world outcomes.
📝 Latest Blog Posts
Localizing Black ICE, the Biggest HOI3 Mod, into Chinese
If We Ask a Team of AIs to Prove Mathematical Theorems, What Kind of ‘Company’ Should We Build?
🎮 Hobbies
The hobbies listed below are not only things I consume: every now and then I build something for them. The biggest of these detours is a Chinese localization of a strategy game I have been playing since high school.
黑冰中文版 · Black ICE Chinese — a Chinese localization of HOI3 Black ICE
A free, non-profit fan project that merges Black ICE — the largest English mod for Hearts of Iron III — with the community’s Chinese localization of the game, with the goal that it simply opens in Chinese and can be played from start to finish.
- Why: I played HOI3 for over a thousand hours across high school, university and graduate school, and Black ICE was always my favourite: supply is unforgiving, industry is a real planning problem, and the order of battle of a single armoured corps can eat an afternoon. But my English could not keep up with the reading — three hours of play meant two hours in a dictionary.
- What it took: the engine only understood 8-bit glyphs, so Chinese could not be displayed at all. The project patches
hoi3_tfh.exeto read 16-bit glyphs (42 patch sites plus an 8 KB new code section), fixes a guaranteed0xC0000005crash caused by one wrongly sized register, and turns on the 4 GB address space so late-game saves stop running out of memory. - Where it stands: 80,195 of 83,751 localization strings translated (95.8 %); general names, unit designations and cabinet ministers at 100 %. Weapon models and specifications are deliberately left in English.
- Also: a small, checkable sample of human–AI collaboration — the tools, the hours and the token usage are recorded in the repository’s
ABOUT.md.
🌱 About Me
Cheerful, optimistic, and thrives on tackling challenging tasks. Passionate about Go (WeiQi), gaming, and football.
- Go (WeiQi): roughly 7 dan amateur on Fox Weiqi (野狐围棋).
- Gaming: my long-time favorite is StarCraft II — I once reached Master league on the China server.
- Football: lifelong fan of Borussia Dortmund, with Marco Reus being my favorite player.
One funny coincidence I cannot help noticing: almost everything I happen to love — Go, StarCraft II, football — has at some point become a research target of DeepMind. That coincidence is part of why I deeply believe in the power of AI. My goal is to push the frontier of AGI through reinforcement learning, game theory, and multi-agent systems on top of large language models, on both the research side and real-world applications.